Stay Close to the Metal

summary
Argues that productivity comes from picking one measurable LM task and iterating close to the metal: the team builds a topic‑detection pipeline, runs Llama.cpp local 7B for fast offline vibe checks and cosine/purity/dot‑product metrics, packages inference with Ray Serve on Kubernetes, hits a package import bug, isolates a minimal reprox in Ray’s private utils and fixes it, and ships a production endpoint in about two weeks; claim: narrow task + local reprox + concrete metrics keeps LLM work manageable.
AI-written summary · about
chapters (13)
- 0:00Introduction and context
- 2:30Approaching AI problems
- 6:36The analogy of gradient descent
- 9:25Understanding gradient descent
- 14:21Defining the core task
- 17:25Finding focus and simplicity
- 21:29Applying Unix philosophy
- 25:07Evaluation strategies
- 28:26Engineering reproducibility
- 32:18Distributed systems and Ray
- 37:27Productionizing the solution
- 40:36Retrospective and core lessons
- 43:33Q&A session
related talks
 01h 02mTools for simplified large scale systems
 26mMLOps for the rest of us- A poor man's guide to putting models in production
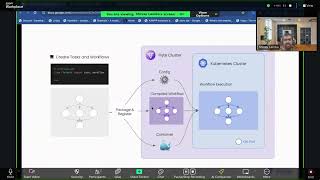 25mFine-Tuning Large Language Models With Declarative ML Orchestration
 23mLive Q&A
 39mUnderstanding minimal viable quality promotes craft
 15mResearch to Reality: Bringing Frontier ML Research to Production
 30mBuilding Teams and Culture that Support ML Innovation
 01h 13mPractical MLOps- Do we need all the things