You Only Linearize Once: Tangents Transpose to Gradients

summary
Claim: reverse-mode AD is exactly forward-mode AD followed by unzipping the forward result into nonlinear and linear parts and then transposition of that linear part, formalized as You Only Linearize Once. Work builds a Linear A language, a substructural linear type system, and a cost model; proves forward-mode output is linear, unzipping and transposition preserve work and correctness, and double-transpose is identity. Implementation experience in JAX and Dex shows fewer reverse rules required, checkpointing appears as a choice in unzipping, and the decomposition simplifies real systems.
AI-written summary · about
chapters (11)
- 0:00Start
- 4:38It is complicated!
- 9:46Linear A
- 11:26Type system
- 12:33Structural and algebraic linearity
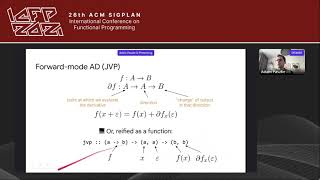
- 14:13Forward-mode autodiff (JVP)
- 15:50Unzipping
- 17:38Transposition
- 19:15Insight: checkpointing is not inherent to AD
- 20:30Insight: AD as a language design benchmark
- 20:58Insight: simplifying AD system implementations
related talks
 10mReverse mode ADEV via YOLO: tangent estimators transpose to gradient estimators
 23mContextual source code AD transformations for sum types
 01h 21mNon-local compiler transformations in the presence of dynamic dispatch
 29mParallelism-preserving automatic differentiation for second-order array languages
 27mProvably Correct, Asymptotically Efficient, Higher-Order Reverse-Mode Automatic
 36mProgramming Languages for Automatic Differentiation: What Now?
 11mAbstract Interpretation for Automatic Differentiation
 29mPartial Evaluation of Automatic Differentiation for Differential-Algebraic Equati...