Transforming your Jupyter Notebook to a Reproducible Machine Learning Pipeline using Kale
summary
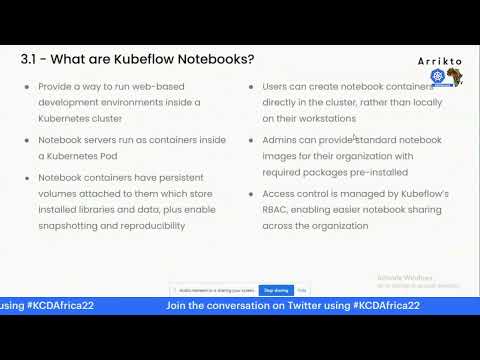
Demo converts a digit recognizer Jupyter notebook into a running Kubeflow pipeline using Kubeflow Kale and the Kubeflow Pipelines UI and notebook server. Steps become components: download, load, preprocess, train, predict, with a volume created and a pipeline run taking about ten minutes and training set to two epochs. Output includes a saved model and a confusion matrix in the UI, showing the pipeline is reproducible and portable as Jupyter notebook→pipeline execution.
AI-written summary · about
chapters (4)
related talks
 25mScaling ML pipelines with KALE — the Kubeflow Automated Pipeline Engine
 01h 27mTutorial: From Notebook to Kubeflow Pipel...
 05mLightning Talk: Build a Reproducible ML Workflow with Kubeflow Pipelines
 49mTutorial: From Notebook to Kubeflow Pipelines to KFServing: the Data Science Odyssey
 15mKeynote: Machine Learning on Kubernetes Made Easy With Kubeflow
 35mOrganizing data engineering around Kubeflow
 29mComputer Vision Dog Breed Classification with Convolutional Neural Networks, TensorFlow and Kubeflow
 36mMachine learning pipeline Kubeflow, let's start