What It Really Means for Your System to Be Available

summary
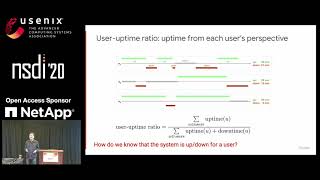
Defines availability in concrete SLO terms rather than slogans: shows how 99.9% availability becomes a 1% error budget on a rolling 30‑day window and how using burn rate ≈1 informs safe deployments. Explains pairing latency thresholds (e.g., 3s) with percentile targets and lists concrete metrics per service—availability/latency/quality for request-driven services and coverage/correctness/freshness/throughput for data pipelines—plus a revenue‑weighted uptime metric used to reorder roadmaps and reduce incidents in a payments stack.
AI-written summary · about
chapters (9)
- 0:00Introduction
- 1:05Speaker background
- 3:57System reliability definition
- 8:37Error budget concept
- 15:02SLO framework benefits
- 21:30Recommended metrics
- 32:24Implementing SLO in team
- 37:43SLO at Facebook example
- 46:01Q&A