News from Flink’s engine room: “Full steam ahead”

summary
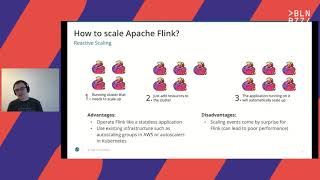
Flink adds a pipeline region scheduler that makes pipeline regions the atomic unit for scheduling and failover and avoids deadlocks when resources are constrained; FLIP-1 (shipped in Flink 1.9) already enables stage-wise recovery and faster batch job restarts; declarative resource management via FLIP-138 changes slot allocation to request “as many slots as possible” and underpins a reactive execution mode that lets jobs auto-scale as TaskManagers register (targeting experimental releases around 1.12–1.13).
AI-written summary · about
chapters (6)
- 0:00Introduction
- 0:27Unifying batch and streaming
- 5:24Fine-grained recovery in Flink
- 11:06Scheduling challenges and fixes
- 18:35Elastic streaming pipelines
- 32:19Conclusion and Q&A
related talks
 44mFlink’s New Batch Architecture
 20mAutoscaling Apache Flink Applications
 18mTowards More Efficient and Adaptive Scheduling for Flink Batch
 31mRethinking of fault tolerance in Flink: what lies ahead?
 43mStream Processing and Applications in the Modern Age
 33mFlink and Beam: Current State & Roadmap
 42mApache Flink deep-dive #bbuzz
 37mWhat's new in 1.9.0 blink planner