Flink + Pulsar: The Path To Unified Batch and Streaming
summary
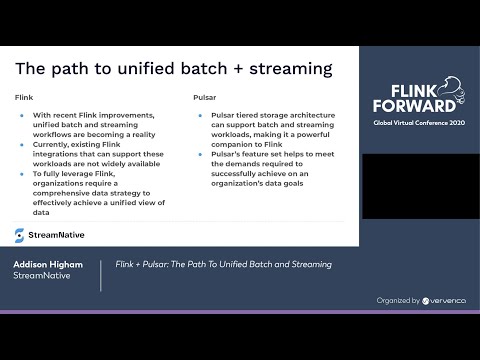
Flink reads from Pulsar with native tiered storage and segments offloaded to S3, enabling parallel batch reads from closed segments and seamless transition to streaming. Pulsar adds Key_Shared subscriptions so a Flink job can use more consumers than partitions, preserving per-key ordering. A maintained Pulsar–Flink connector supports Flink SQL, uses the reader API, and aims for upstream inclusion around Flink 1.13; Pulsar targets transactions (2.7), columnar offload for predicate pushdown, and BIGO runs at 2–3 GB/s ingest serving 100M+ users.
AI-written summary · about
chapters (9)
- 0:00Introduction
- 8:07Why Flink Pulsar
- 14:45Leveraging Flink Pulsar
- 17:45Pulsar Client
- 18:35Pulsar Reader API
- 19:15Pulsar Recap
- 20:55Pulsar Overview
- 23:45Pulsar Adoption
- 25:45Pulsar Integration
related talks
 54mApache Pulsar Development 101
 32mStreaming Analytics with Apache Pulsar
 46mApache Pulsar: Finally an Alternative to Kafka?
 51mEvent Streaming and Processing with Apache Pulsar
 23mBetter, Faster, Stronger Streaming: Your First Dive into Flink SQL
 40mThe Seven Deadly Sins of Streaming
 43mUnified stream and batch processing with Apache Flink’s relational APIs
 46mConnecting Apache Flink and the Pravega Stream Store