Building a Self-Service Streaming Platform at Pinterest
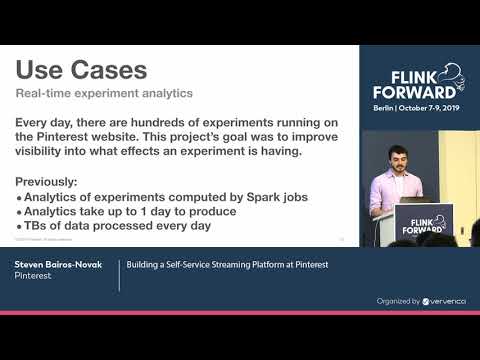
summary
Pinterest standardizes a Flink-based self-service streaming platform running Flink on YARN that replaces ad-hoc Kafka Streams and Spark micro-batches, handling terabytes per day and over a trillion Kafka messages companywide. Built features include a history-server tweak that embeds YARN application IDs and taskmanager→container mappings so web links go straight to YARN log pages, and a backfill system that replays S3-backed Kafka backups (Merced files) and uses a savepoint trick to transfer operator and source offsets from backfill to live Kafka; the approach works but restart is manual today.
AI-written summary · about
chapters (7)
- 0:00Introduction
- 1:07Background on Pinterest
- 3:59Choosing a streaming engine
- 6:31Use cases for Flink
- 12:19Challenge one log access
- 22:46Challenge two backfilling
- 34:41Future plans and summary
related talks
 29mA brief history of time with Apache Flink
 46mScaling Pinterest
 35mKeynote: Stream analytics made real with Pravega and Apache Flink
 34mKeynote | Flink Ahead 2.0: The Sequel
 25mMixing data streams at scale
 43mBuilding a community fountain around your data stream
 42mHow Netflix Built a Real-Time Distributed Graph for Internet Scale
 37mMeasuring 2.0 – Building the next generation webanalytics ...