"Range as a Key" is the Key! Fast and Compact Cloud Block Store Index with RASK

summary
RASK is a tree-structured cloud block-store index that natively uses range-as-a-key with adaptive radix tree internals and B-tree cell leaves, a log-structured leaf for append-only updates, ambulation-based reverse search, and a two-stage GC plus range-aware split/merge to cut overlap and fragmentation. Implementation evaluates on four production traces (Alibaba, Google, Meta, Tencent) and reports up to 98.9% memory reduction and up to 31.0× throughput improvement versus ten state-of-the-art indexes, code and traces released.
AI-written summary · about
chapters (11)
- 0:00RASK introduction
- 2:24Range writes analysis
- 4:32Traditional vs range indexing
- 5:34RASK design
- 6:58Handling range overlap
- 9:05Garbage collection in RASK
- 10:11Range fragmentation
- 12:38Workload-aware merge
- 13:21Evaluation setup
- 13:43Performance results
- 14:46Summary
related talks
 12mROART: Range-query Optimized Persistent ART
 23mSRFI-167, SRFI-168 and the functional store
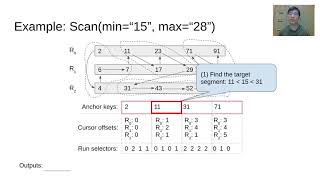 12mREMIX: Efficient Range Query for LSM-trees
 17mArctic: A Practical Lock-Free Adaptive Radix Tree
 16mScaleDB: A Scalable, Asynchronous In-Memory Database
 38mLight and Adaptive Indexing for Immutable Databases
 24mARKDB: The Key-Value Engine for Alibaba Cloud Storage Services
 25mAC-Key: Adaptive Caching for LSM-based Key-Value Stores