Big‑T Notation: Engineering for Token Efficiency in the Age of Enterprise AI
summary
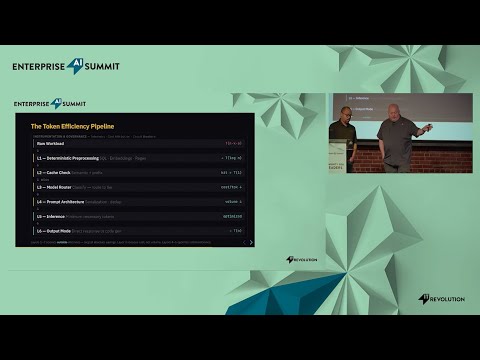
Introduces Big‑T Notation as a practical metric decomposition — requests × models per request × agent depth — and shows concrete wins: database views and prefiltering cut calls by 92% or more, token-aware serialization yields 40–60% serialization savings, and some RAG/caching setups report >99% reductions for repeated queries. Recommends routing cheap models for routine tasks, treating code as the new code as cache layer to compress natural language, and avoiding vendor credit abstractions that hide per-token cost and block measurable optimization.
AI-written summary · about
chapters (8)
- 0:00Introduction
- 1:00The Token Cost Problem
- 4:02Big-T Notation Framework
- 5:56Code as Cache Layer
- 9:14Model Routing and Prompt Structure
- 11:53Token Caching and Vendor Transparency
- 14:08Layered Efficiency Stack
- 17:51Key Takeaways
related talks
 06mYour Agent Is Wasting Tokens and You Don't Know It
 31mAI Coding Agents Don't Need Bigger Models. They Need Better Tools.
 16mThe Real Cost of a Token: The Hidden Bill of Generative AI
 11mWe Cut 94% of AI Coding Tokens With a Local Code Index
 32mAI Engineering Anti-patterns
 32mFrom Three Days to One Minute: Architecture Trade-offs in Production Enterprise AI
 20mFireworks AI: Go from Hype to High - Value AI
 18mTrends Across the AI Frontier