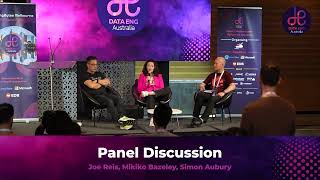
Panel Discussion

summary
Argues data engineering expands beyond pipelines into data modeling and ongoing quality work, with concrete ML pitfalls like target leakage and distribution shift that break models; highlights communication fixes via GitHub PRs and Conway’s Law; gives MailChimp example: moved some workloads to GCP, kept a revenue-critical shard on-prem and built a new ML stack after a brittle R script spam model; warns about LLMs’ hallucinations and that RAG doesn’t eliminate human review, and recommends orchestration and cross-team incentives.
AI-written summary · about
chapters (13)
- 0:00Panel introduction
- 1:04Data engineering skills 2023-2024
- 3:59ML use case engineering
- 7:25Attitude and learning
- 9:09Engineering team communication
- 12:43Conway's law in data teams
- 14:07Measuring data platform success
- 17:58Data infrastructure evolution
- 21:05Legacy system migration
- 24:17Cloud migration FOMO
- 26:48Tech obsessions and adaptability
- 28:14Career advice for data engineers
- 30:39AI tools for workflows
related talks
 31mPanel Discussion
 45mMixed Model Arts
 02mThe Future of Data Science/ML at Scale
 51mPanel Debate: Rise Of The Data Engineer
 25m"Data Engineering: The World Between Worlds"
 50mThe future of Data Engineering panel
 26mUnlocking the Power of Data-Centric AI.
 26mApplying DevOps practices in Data and ML Engineering