Scaling Kafka on Kubernetes

summary
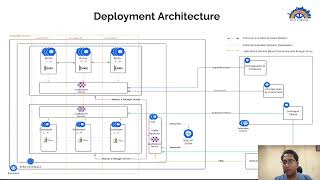
Claims sustained 100,000 messages per second with <5 ms P99 latency and ~99.9% availability using Kubernetes primitives: Kafka as StatefulSets, SSD-backed PVs, XFS with tuned mount options, CPU requests of 2–4 CPU cores per broker and 8–16 GB heap, HPA driven by consumer lag and partition throughput, MirrorMaker for cross-region replication, GitOps CI/CD for automated rollouts and rollbacks, and Prometheus/Grafana monitoring; rolling upgrades, autoscaling and disaster recovery are demonstrated end to end in production.
AI-written summary · about
chapters (15)
- 0:00Introduction to Kafka on Kubernetes
- 0:32Understanding the Problem Space
- 1:11Why Choose Kafka on Kubernetes?
- 2:06Key Pillars of Kafka on Kubernetes
- 3:08Resource Allocation Strategies
- 4:06Optimizing Storage for Kafka
- 5:13Enhancing Network Performance
- 6:02Auto Scaling Kafka Clusters
- 7:00Multi-Cluster Deployments
- 7:50Operational Excellence with GitOps
- 8:35Monitoring and Metrics
- 9:24Performance Metrics and Achievements
- 10:28Disaster Recovery Strategies
- 11:38Conclusion and Key Takeaways
- 12:39Q&A and Further Discussion
related talks
 42mProcessing Millions of Events per Second with Apache Kafka on Kubernetes
 35mKafka Deployment at Scale
 24mMake Your Kafka Cluster Production-Ready
 31mEvent driven communication with Kafka on Kubernetes
 26mProduction Grade Kafka on K8s
 53mDemystifying Kafka
 47mRunning Kafka in Kubernetes: a practical guide
 27mRunning Kafka in Kubernetes a practical guide