Juggling Petabytes: Managing Ceph at Scale with Ceph-ansible

summary
Operates a single Ceph cluster built from Supermicro nodes with 18 PB raw capacity and about 40% used, deployed and managed with ceph-ansible plus local playbooks for bonding, Let’s Encrypt and RADOSGW user ops; hits ~100 GB/s read in internal rados bench runs; uses NVMe for DB/WAL and saw ~25k metrics/server under luminous; migrates OSDs from filestore to BlueStore with a per-host conversion that can take ~30 hours and stalls on large OMAPs; adds scripts to blink drive bays and automate replacements and notes pain points around shard rebalancing, erasure-code migration and pool shrinking.
AI-written summary · about
chapters (8)
- 0:00Introduction and background
- 4:38Institute overview and storage needs
- 8:59Ceph cluster hardware and growth
- 13:54Monitoring and metrics with Ceph
- 20:39Benchmarking and upgrades
- 24:08Pain points and challenges
- 31:18Ceph reliability and expansion
- 39:18Q&A
related talks
 28mA Welcoming Ceph Experience Improvements for First-Time Users or: How to Make Beginners Love Ceph
 44mContainer Management at Scale
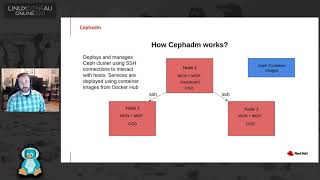 16mTips and Tricks for Managing and Administering Ceph Clusters
 20mEnterprise-Ready Ceph: Simplifying Storage Management, Operations, and Deployment
 29mTowards Sustainable Multi-Cluster Management in Real-World Academic Infrastructure
 10mCluster-scale Problem Solving
 28mCeph Performance: The Basics of Tentacle Racing
 22mDeepSea: Deployment and Management of Ceph with Salt