Getting AI to Forget About You: Data Deletion From Machine Learning Models

summary
Shows that trained models must sometimes remove individual records on demand, and formalizes deletion as a mapping that returns the model as if the point were never seen. Linear regression supports O(d^2) deletion by updating XX^T and X^T y; k‑nearest neighbors and hierarchical and quantized clustering let deletions touch only local subtrees. Gradient descent and SGD are provably hard to unwind. Prototype algorithms report 4 orders of magnitude faster amortized deletion than naive retraining.
AI-written summary · about
chapters (4)
- 0:00Start
- 4:58Beyond privacy: data governance
- 6:52Data deletion is fundamental to data governance
- 25:50Deletion efficiency
related talks
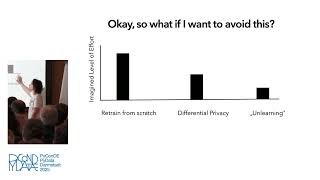 30mUnforgettable, that's what you are: Evaluating Machine Unlearning and Forgetting
 32mThe Importance of Forgetting for Both Humans & Machines
 46mIncreasing Participant Agency by Understanding the Impact of Training Data
 15mLearning and Unlearning Your Data in Federated Settings
 23mHow can a learnt ML model unlearn something: Framework for "Machine Unlearning"
 24mData Governance in the AI age
 45mApplied machine learning: a few lessons I learned the hard way
 39mChanging Realities - The Final Frontier for Machine Learning?