Vertex AI: Pipelines for your MLOps workflows

summary
Vertex AI Pipelines demonstrates a managed, serverless ML workflow that removes most infrastructure overhead and compiles Python pipeline definitions to a JSON pipeline that can be triggered by scheduler, Cloud Build or Eventarc. Demo uses a 600‑image dataset with an AutoML image model that trains in 28 minutes and serves as a REST endpoint with ~1–5s latency, supports batch predictions, a model registry, feature store and metadata, and pipeline caching so reused steps skip rerun and export to Cloud Run or use Vertex AI Pipelines for orchestration.
AI-written summary · about
chapters (15)
- 0:00Start
- 2:45Pipeline Automation
- 10:03Custom Models
- 10:36Bigquery Machine Learning
- 14:54Home Screen
- 17:09Demo
- 17:42Latency
- 20:27Why Are Pipelines Useful
- 25:25Google Cloud Pipeline Components
- 29:02Caching
- 29:35Recap
- 32:41Cloud Workflows
- 33:31Conclusions
- 40:13Data Pre-Processing Pipelines
- 41:16Data Pre-Processing
related talks
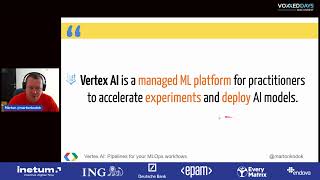 31mVertex AI: Pipelines for your MLOps workflows
 40mVertex AI: Pipelines for your MLOps workflows
 12mBuild end-to-end solutions with Vertex AI
 26mBuilding Portable ML Pipelines for Development and Production
 03mML Ops on Google Cloud
 30mAI in the Cloud
 18mBuilding Efficient PyTorch Models on Vertex AI
 51mHands on with Cloud AI