What's next for BDAS?
summary
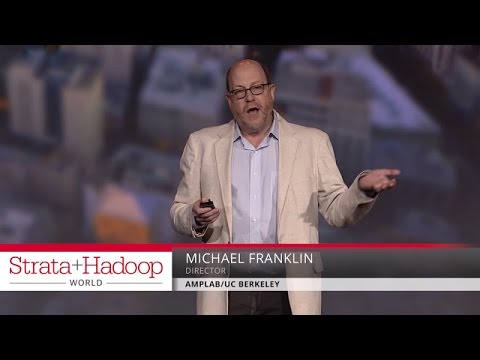
Berkeley Data Analytics Stack adds three concrete systems: Succinct stores compressed data that supports regex and numeric queries without full decompression, lets you trade compression for CPU, and supports encrypted and graph compression; Velox splits models into a Spark-computed global component plus thousands of tiny per-entity models to serve low-latency personalized predictions for recommendations, fraud, IoT; KeystoneML auto-selects algorithms, materialization and caching across pipelines, runs on multi‑terabyte jobs at ~100 nodes and exposes new operators and auto‑tuning.
AI-written summary · about
chapters (6)
- 0:00Start
- 0:45Succinct: Queries on compressed data
- 1:40Velox Model Serving
- 2:24Velox Split-Model Processing
- 3:30KeystoneML: ML Pipelines
- 4:30KeystoneML: Status
related talks
 23mAnalystANGLE
 01h 17mData Engineering in the AI Era: Building a Robust Foundation for AI Applications
 13mCombining algorithms and quality data to build better AI platforms
 21mAnand Pradhan, ICE | Databricks Data + AI Summit 2024
 30mSparkless Patterns: The New Data Stack and Modern Data Architecture
 45mManaging Data & Analytics Projects Effectively
 41mBig data as we know it @bol.com
 55mAzure SQL database, Azure Synapse Analytics, Azure Databricks?