Building 3D Trusted Data Pipelines With Dagster, Dbt, and Duckdb
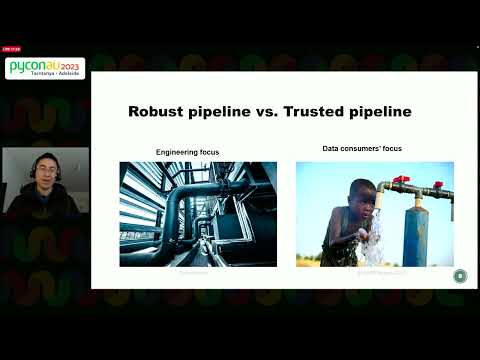
summary
A concrete ELT demo uses Dagster, Dbt, Duckdb to build and validate pipelines: Python ingestion loads three raw tables (payment, order, customer) into DuckDB, dbt transforms to staging and mart layers, and dbt-utils plus dbt-expectations run data-quality checks (18 tests reported and passing in the demo). Orchestration and software-defined assets live in Dagster, runs materialize the lineage, and the complete demo and GitHub repo are published for cloning and replay.
AI-written summary · about
chapters (9)
- 0:00Introduction to the 3D stack
- 2:40Data engineering best practices
- 8:07Modern data stack overview
- 11:03Data testing with dbt
- 13:57Testing tools and techniques
- 17:16Project architecture demo
- 18:34Dbt code and testing demo
- 25:30Dagster orchestration demo
- 28:50Building data trust and wrap-up
related talks
 29mHow to make public data more accessible with "baked" data and DuckDB
 26mBuilding Data Lake Using DuckDB
 22mDuckDBT: Not a database or a dbt adapter but a secret third thing
 24mMake data central feature
 27mThe Duck and the DataFrame: A Data Engineer’s Journey with DuckDB
 41mModular & Reusable: A Recipe to Scaling Data Across a Portfolio
 05mBuilding Tecton’s Feature Engineering Platform on DuckDB
 28mYour Pipeline as a Function.