Natural Language & Search, Improve your Search w/ Vector capabilities
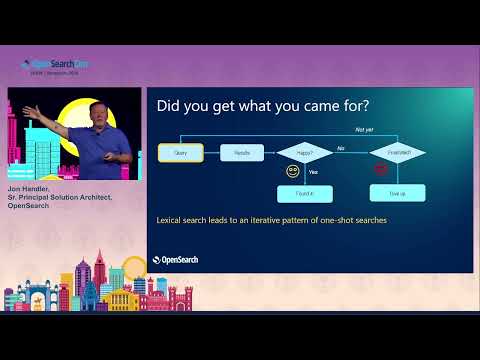
summary
Covers concrete OpenSearch features and Intuit production usage: explains BM25 lexical scoring alongside dense and sparse vectors, shows sparse giving ~10–17% lift over BM25 and ~14% over dense, and describes the neural plugin and ML connector for on‑index or external embedding generation. Details include chunked ingest pipelines, HNSW/IVF indexing knobs, score normalization for hybrid (3:7 lexical:semantic) queries, prefiltering to hit ~200–300 ms, and Intuit’s pipeline indexing bursts at 30k documents/sec with ~40k QPS and ~80% accuracy.
AI-written summary · about
chapters (5)
- 0:00Language and search history
- 10:56Lexical search limits
- 20:43Vectors capture meaning
- 33:09Semantic vs keyword search
- 42:05Vector search best practices
related talks
 32mBudget Friendly Semantic Search With Neural Sparse Search
 48mUnlocking Next-gen Semantic Search With OpenSearch 3.x
 32mRetrieval Augmentation and Semantic Search at Scale
 01h 09mVector Search: Ask Me Anything!
 37mLexical, Vector & Hybrid Search with Elasticsearch
 42mResearch in the Age of AI
 30mVector Search Made Simple: Getting Started with OpenSearch for AI Applications
 59mContextual search with vector search: exploring your options with open source tools