Serena Yeung, PhD Student, Stanford at MLconf Seattle 2017
summary
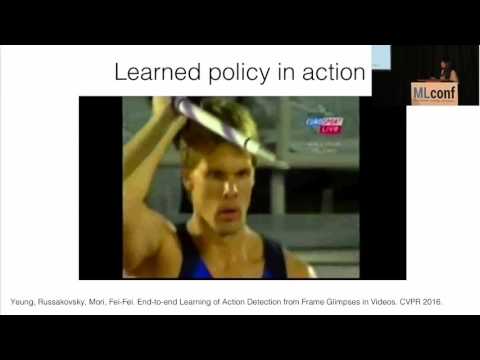
Presents three concrete systems: an RL-based action detector that observes 2% of frames and matches dense sliding-window accuracy by outputting where to look next and when to emit predictions; a MultiLSTM model with expanded input/output temporal receptive fields and attention that improves dense multi-label framewise prediction on a new dataset MultiTHUMOS 30 hours 40,000 annotations 65 classes (1.5 labels/frame, up to 9 co-occurring actions/frame); and a data-selection policy trained with REINFORCE that picks diverse web-query videos, reduces semantic drift, and transfers to novel classes.
AI-written summary · about
chapters (17)
- 0:00Intro
- 1:09State-of-the-art in video underst
- 2:26Comparing video with image unders
- 5:16Task: Temporal action detec
- 5:36Efficient video processin
- 7:00Our model for efficient action detec
- 9:34Learned policy in action
- 11:33Dense action labeling
- 13:11Modeling dense, multilabel
- 13:53MultiLSTM
- 15:16Retrieving sequential act
- 15:49The challenge of scale
- 16:24Labeling videos is expen
- 16:41Web queries are a source of noisy vide
- 19:09Overview of approach
- 22:38Novel classes
- 24:22Towards Knowledge
related talks
 32mEverything you wanted to know about VLMs but were afraid to ask
 31mLayla El Asri, Research Scientist, Maluuba, NYC 2017
 17mAI/ML demo derby
 46mML Use Cases at Think Big Analytics
 32mVideo Action Models
 17mLearning Cooperative Personalized Policies from Gaze Data
 32mThe ML system endeavors
 17mRECL: Responsive Resource-Efficient Continuous Learning for Video Analytics