Sampling in Query Evaluation 2

summary
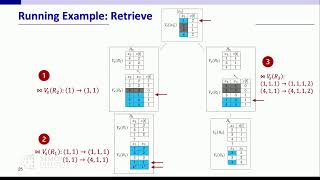
Describes a concrete sampling pipeline for joins that uses the Horvitz-Thompson estimator on join trees: sample tuples down the tree, accept with probabilities that multiply to 1/WR1 after cancelation, and weight each successful path by the inverse path probability to get an unbiased sum estimator; provides a Horvitz-Thompson variance estimator and confidence bounds via CLT/Hoeffding/Chebyshev. For cyclic queries it proposes splitting into acyclic vs cyclic parts and exhaustively counting Q_rest per join key. Main theoretical claim is a FPRAS for #TA and thus for counting answers to acyclic conjunctive queries.
AI-written summary · about
chapters (10)
- 0:00Sampling in acyclic queries
- 1:17Horvitz-Thompson for acyclic joins
- 5:57Handling cyclic queries
- 10:39Estimating cardinalities and aggregates
- 22:20Horvitz-Thompson in practice
- 37:49Sampling with projection and selection
- 41:16Tree automata for conjunctive counting
- 55:55Counting accepted trees
- 58:48Open problems and future work
- 1:02:58Q&A
related talks
 47mApproximate Lifted Inference with Probabilistic Databases
 22mImproving PostgreSQL Join Estimates Statistics and Beyond
 33mCombined Approximations for Probabilistic Query Evaluation: An Intensional Approach
 38mIncremental View Maintenance: Beyond Worst-Case Analysis I
 01h 09mAccessing Answers to Unions of Conjunctive Queries with Ideal Time Guarantees: I
 26mIncremental View Maintenance: Beyond Worst-Case Analysis II
 21mRecent Advances in Incremental View Maintenance
 44mIntermediate Relational Algorithm Design