Model Serving at the Edge Made Easier

Talkat Kubernetes on Edge Day Europe 2022 · on Tuesday, 2022-05-17· at 13:35· Pavilion 4, Room C | Level 2 | Central Forum·
summary
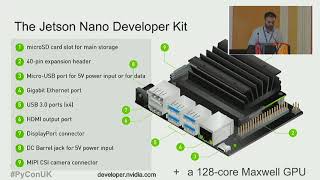
ModelMesh is deployed on a Jetson Nano running MicroShift and registers about 17 DenseNet ONNX models (~36 MB each) as ready; inference is sub-second when a model is loaded and adds several seconds on a cache miss. Architecture uses Triton/MLServer runtimes plus a single pod multi-model runtime with a LRU cache-based model eviction and a sidecar puller. Works well for high-density edge packing, but ARM builds and >1 GB images remain blockers.
AI-written summary · about
chapters (16)
- 0:00Intro
- 0:39Outline
- 1:12Generations of Computing
- 3:41Machine Learning Lifecycle
- 4:02Complexities of Model Serving
- 5:28Kubernetes at the Edge
- 8:06Introducing KServe
- 9:04Easy to Use Interfaces
- 9:32Kserve Standardized Inference Protocol
- 11:09Enter ModelMesh
- 12:49ModelMesh Architecture
- 14:33ModelMesh Serving Runtimes
- 15:21ModelMesh On Edge?
- 19:08Example Deployment
- 21:37Higher Density Deployment
- 25:05Challenges
related talks
 26mBuilding a Cloud Native Edge Platform for Accelerating AI Inference
 36mWhat's New, ModelMesh? Model Serving at Scale
 33mHigh Performance Deep Learning on Edge Devices With
 28mMachine Learning on the Edge
 21mEdge Inference on Unknown Models
 18mModel Serving for Deep Learning
 12mPreview: ML Serving
 36mApplied AI on the edge