Keynote: Reliability in Cloud Native DevOps
summary
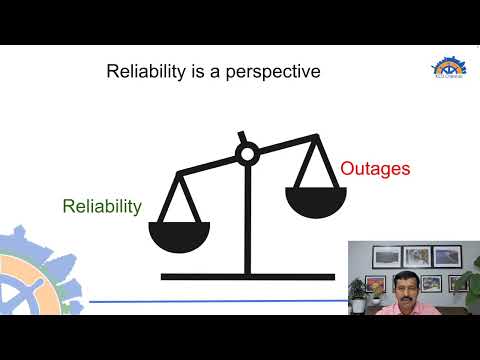
Cloud native reliability requires a chaos-first approach that injects controlled faults across infra, middleware and application layers; Litmus (a CNCF incubating project) provides a chaos center control plane, public/private experiment hubs and more than 50 enterprise releases, letting teams run declarative chaos workflows (YAML) via kubectl apply a chaos workflow, schedule tests in CI/CD, limit blast radius, and measure reductions in time-to-identify and recovery so outages drop and SLOs improve.
AI-written summary · about
chapters (19)
- 0:00Intro
- 2:32Recap: What is Cloud native?
- 4:03What's "new" in Cloud Native?
- 6:29Reliability is a perspective
- 8:15Outages are expensive
- 9:06Impact of outages
- 10:20What causes these outages?
- 12:55Outages in Cloud Native ??
- 18:44Chaos first approach
- 19:33Chaos Engineering 101
- 21:22Chaos Engineering is a DevOps culture
- 22:27Who is involved in Chaos Engineering?
- 25:52Chaos Orchestration
- 26:49Chaos tests for Developers
- 29:22Litmus Usage in DevOps
- 30:08Chaos Maturity Model
- 31:45Chaos Engineering ROI
- 33:39Summary
- 34:39How can you start with LitmusChaos?
related talks
 39mPracticing Cloud-Native Resliency Is a Challenge: Decoding It with Chaos...
 23mChaos Engineering for Cloud Native
 29mCase Study: Bringing Chaos Engineering to the Cloud Native Develo...
 05mProject Lightning Talk: Chaos Unleashed: LitmusChaos and Its Journey Towards CNCF Graduation
 34mChaos Engineering For Hybrid Targets With LitmusChaos
 25mDestroy Your System To Make It More Reliable: An Easy Way To Start Chaos Engineering With LitmusChao
 11mKeynote: Like a Magic Eye Illusion: Seeing the Bigger Picture for Cloud-Native S...
 22mAll Clouds Need a Sprinkle of Chaos