From Unreliable to Resilient: Mastering Distributed Systems

summary
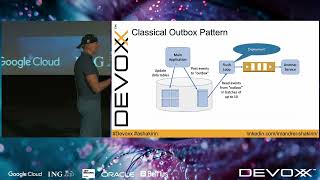
Shows how to survive network failures by writing the event and a message into the same DB transaction and using a relay to push it to the bus, using the Outbox pattern (or binlog tailing) plus an Inbox table for deduplication; accepts at‑least‑once delivery and explains duplicates, compensating actions via the Saga pattern, and two styles: a single orchestrator vs choreography. Describes a simple relay service that reads, forwards, and how monitoring reveals stalls; event sourcing is presented as the scalable next step.
AI-written summary · about
chapters (20)
- 0:00Introduction
- 1:25From monoliths to service-oriented architectures
- 3:13Transactional problems
- 7:02Two-phase commit limits
- 12:37Decisions vs side effects
- 16:29Dual writes challenges
- 18:16Outbox pattern
- 21:06At-least-once delivery
- 25:55Stock discrepancies solutions
- 27:22Saga pattern
- 29:06Orchestration vs choreography
- 37:27Designing for failure
- 39:11Event bus failures
- 41:57Backup mechanisms
- 43:03Immutable events
- 44:04Scaling the conductor
- 46:10Client responses boundaries
- 51:07Distributed monoliths
- 52:34Event sourcing
- 55:21Q&A
related talks
 57mReliability Nirvana
 57mSafe Passage: Messaging in a distributed systems environment
 34mAtomicity and Consistency Across Databases and Messaging Systems
 45mDo Distributed Systems they said. It'll be fun they said.
 17mEnsuring Reliable Distributed Transactions in Logistics
 29mThe art of being resilient. How to handle failures gracefully in Distributed Systems.
 52mDistributed Computing Dealing with Time and Failure in the Wild
 01h 38mBuilding Reliable Distributed Systems