Seeing RED: Monitoring for Microservices and Serverless
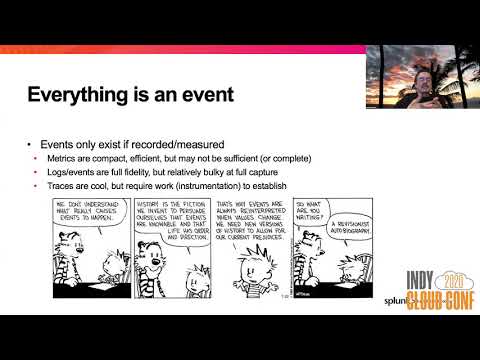
summary
RED (Rates, Errors, Duration) adapts Google’s Golden Signals for microservices and serverless and focuses on concrete checks: Rates, Errors, Duration as triggers, distributed traces via OpenTelemetry, and infrastructure-aware metrics from Kubernetes. Examples include a 1.9% customer workload that floods an ingest queue across 1,500 cores and Lambda cold starts of 400–700 ms versus warm 38–45 ms. The workflow shows automated runbook actions like canary rollbacks, drill-down from rate spikes to thread logs, and the claim that e‑commerce downtime costs can hit ~$300K per minute.
AI-written summary · about
chapters (15)
- 0:00Seeing RED: Observability and Microservices Adventures in Mult-Dimensional Observability
- 1:21World of Operations & App Developr
- 3:30Observability is a Signal to Noise Prce
- 4:32Observability is Not One Dimensiona • Recall Internal States Inferred from External Outputs
- 5:25Observability Isn't Just Monitoring
- 7:28Three Primary Pillars of Observabilit
- 13:20Observability and the Loop Dilemma Even when it isn't a loop
- 20:02A Rate Example
- 21:55An Errors Example
- 23:57Duration Example
- 24:36Why RED?
- 29:32Crossing the Streams It's in the last place you look
- 32:38The Zen of Observability in Services
- 33:49Some Philosophy
- 37:19Summary
related talks
 30mSeeing RED
 35mThe RED Method: How To Instrument Your Services [B]
 35mMonitoring Microservices
 40mMeasuring Micro-services
 34mObservability in Serverless Application
 17mIT Infrastructure Reliability Through Monitoring and Alerting
 51mUSE, RED and Golden Signals for Performance Analysis and Optimization
 47mResolving performance issues in practice