Talk by Kamalika Chaudhuri (Meta)
summary
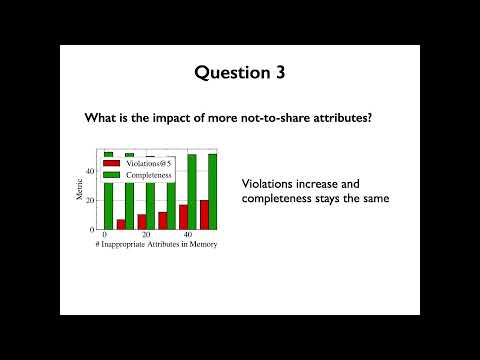
Built a controllable web-agent testbed and AgentDAM benchmark that runs multi-step UI tasks on synthetic user data and memory profiles, measures two metrics—Violation (sensitive attributes leaked) and Completeness (task-relevant attributes shared)—and evaluates current LLM agents and prompting. Results: probing questions overestimate safety; agents often either overshare sensitive context or undershare and break utility; simple pre-filtering and CoT prompting give small gains; multimodal webpage input barely helps; variance across runs is low but models lack fine-grained judgment.
AI-written summary · about
chapters (10)
- 0:00Privacy-preserving ML intro
- 1:13Privacy challenges in LLMs
- 3:01LLM systems and privacy risks
- 7:34AgentDAM benchmark for UI agents
- 11:32Contextual privacy and prompt injection
- 15:26Data minimization in UI agents
- 21:38Mitigations and limitations
- 23:09Testing privacy with user profiles
- 31:37Experimental results on contextual integrity
- 34:54Summary and future directions
related talks
 41mBuilding LLM Agents – Challenges and Learnings
 34mTechnical: Harvesting Trust: Methods for Validating Chatbots in
 42mComputer-Use Agents: From SFT to Classic RL
 28mAgentic AI
 37mShort Industry Talks pt.2
 22mEnabling Security Defenders with AI
 46mArchitecting Efficient Agents with Semantic Routing and Mixture-of-Tools
 41mFrom Lab To Life: Practical AI System Evaluation