AI for Java Developers - From Buzzword to Code
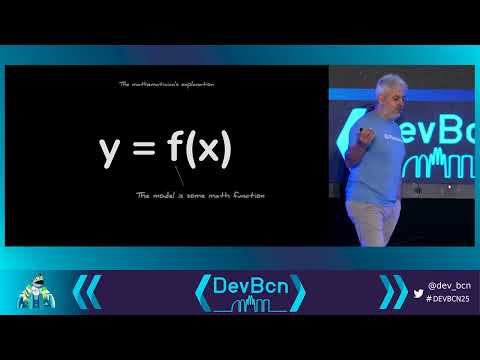
summary
Demonstration converts book descriptions into embeddings stored first in Postgres (vector extension) and then in a Pinecone index (about 1,600 items), comparing naive word-based vectors to model embeddings from a MiniLM packaged as a jar and loaded by LangChain4J. A local LLM path uses tiny-llama 1.1B via JLlama and a faster option runs Llama 3.2 through Ollama; model generation takes ~73 seconds on a modern laptop (5–6 minutes on older Intel). Retrieval-augmented generation (RAG) returns accurate store results and prevents hallucination.
AI-written summary · about
chapters (14)
- 0:00Introduction and speaker intro
- 3:42What is AI for Java devs
- 9:01Demo: Text search with PostgreSQL
- 13:24Tokenization and embeddings basics
- 17:47Vector distances and similarity search
- 23:12Training models and embeddings
- 25:24Using models in Java with LangChain4j
- 30:47Vector databases like Pinecone
- 34:01How LLMs predict next words
- 36:09Demo: TinyLlama with Jlama
- 39:20Ollama for running models locally
- 42:56AI services and agents
- 45:43RAG: Retrieval Augmented Generation
- 50:39Summary and next steps
related talks
 42mBuilding AI Powered Applications with Java
 55mAI in Java? Meet LangChain4j and Build Intelligent Services
 01h 03mBuilding AI powered Applications with Java
 46mGenerative AI and Java
 46mAI-powered Java Developers
 27mAI Demystified Unveiling the Intelligence Behind the Machine
 46mBuilding Powerful GenAI Apps with Pure Java
 50mLook Inside a Large Language Model to Become a Better Java Developer