Baby Demuxed's First Assembly Language Function
summary
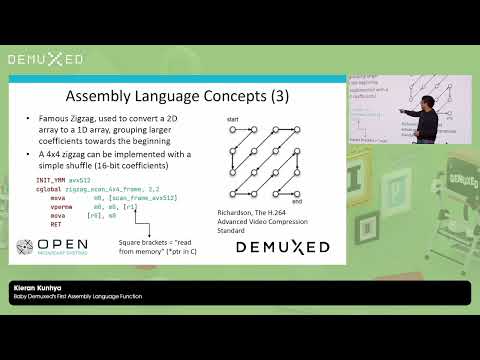
Handwritten x86 SIMD functions claim 10–20x speedups for common video kernels and a pixel packing routine measures 62x faster than C. Example code uses SSE2 XMM registers, explicit loads, PSHUF, unpack interleave, loop unrolling and LEA, and implements pred_8x8 that runs about 2x faster than C. The build includes FFmpeg/x264 integrations, a checkasm test suite for correctness and benchmarks, and real-world results that materially reduce CPU and cost.
AI-written summary · about
chapters (12)
- 0:00Introduction
- 0:47What is ASSEMBLY
- 1:39Why does this matter
- 3:14The pandemic
- 3:36Registers
- 4:29Shuffles
- 5:38Simp
- 8:06Assembly Function
- 8:36Loop Structure
- 9:31InitXMM
- 10:41Loop unrolling
- 11:11Pixel packing
related talks
 52mAdvanced SIMD Algorithms in Pictures
 01h 08mAn implementer's view of Boost.SIMD
 01h 00mJust-in-Time Compilation
 45mFreaking computers, how do they work?
 01h 06mSIMD in C++20: eve of a new era
 33mxsimd: from xtensor to firefox
 01h 06mUtilize your CPU power
 42mFaster programs with your compilers autovectorization feature