How to scale Neural Network Architecture Search with RabbitMQ and Kubernetes
summary
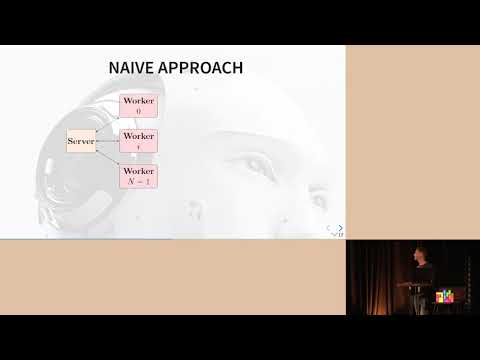
Dvolver runs a population‑based genetic NAS optimizing speed and accuracy on ImageNet, generating independent training jobs so evaluation scales horizontally. The pipeline uses RabbitMQ and Kubernetes with Docker on GCP, leverages preemptible instances and worker autoscaling, and finds microblock architectures in a nontrivial search space. Measured results: 40x speed‑up versus the AutoML baseline, walltime drops from 50 days to 2 days, and cloud cost falls about 60%.
AI-written summary · about
chapters (15)
- 0:00Introduction
- 1:30Context
- 2:56Model Optimization
- 4:47Objective Optimization
- 5:58Project Details
- 6:45Main Advantage
- 7:12The Naive Approach
- 8:13What is RabbitMQ
- 8:37Why we use RabbitMQ
- 9:23Kubernetes Communities
- 9:44Pros of Kubernetes
- 10:07Running the problem
- 11:02Results
- 11:53Final Results
- 12:16Conclusion
related talks
 33mScalable LLM Inference on Kubernetes With NVIDIA NIMS, LangChain, Milvus and Flu...
 27mHarnessing Kubernetes for Scalable AI/ML Workloads
 34mDemocratizing Machine Learning on Kubernetes [I]
 34mDeep Learning at Scale
 27mGen-AI at Scale: Simplifying Orchestration of Healthcare Applications Across Multi-Cluster Environme
 35mReddit's ML Evolution: Scaling with Ray and KubeRay
 25mEmpowering AI-Driven Drug Discovery: Overcoming Challenges in Building a ML Platform on Kubernetes
 28mProductionizing Machine Learning Models at Scale with Kubernetes