Building A Governed Data Lake
summary
Claims a governed data lake built on Snowflake that keeps one copy of data, runs across clouds, and charges by the second while offering RBAC, dynamic masking and ACID. Demonstrates external tables over Parquet on S3 where a 1 billion‑row query takes ~1:08, a partitioned date range query ~20s, and creating a materialized view reduces an aggregate to sub‑second on 7.6M rows. Shows continuous ingestion via Snowpipe, CDC and orchestration with streams and tasks, Hive metastore sync, Spark and Kafka connectors for production pipelines.
AI-written summary · about
chapters (13)
- 0:00Intro
- 0:24CURRENT STATE OF DATA LAKE
- 1:54CHALLENGES WITH DATA LAKE
- 3:54TRADITIONAL DATA ARCHITECTURE Complex, Costly, and Constrained
- 4:44SNOWFLAKE CLOUD DATA PLATFORM
- 6:15SNOWFLAKE ARCHITECTURE
- 7:13SNOWFLAKE FOR DATA LAKE Integrated Data Pipelines with Extensibility
- 9:49BASIC ARCHITECTURE
- 10:23TRADITIONAL DATA WAREHOUSE
- 13:12TRANSFORMATION OF DATA DESTINED FOR SNOWFLAKE
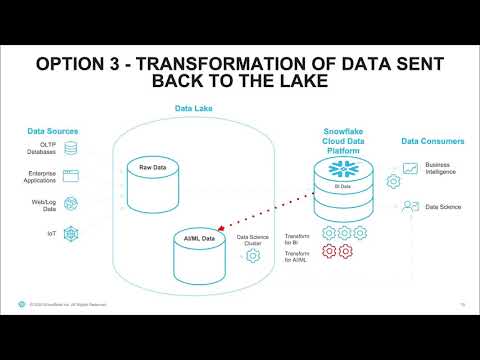
- 14:03TRANSFORMATION OF DATA SENT BACK TO THE LAKE
- 14:58SNOWFLAKE IS FULL DATA LAKE
- 15:39SNOWFLAKE FEATURES THAT HELP
related talks
 51mHow to Build a Modern Data Lakehouse?
 43mManaging a Data Lake on AWS
 25mBuild open format data lakehouse
 41mOn Data: Sky above, sand below, peace within
 26mModernize your Enterprise Data Warehouse & generate value from data
 01h 03mReinvente su estrategia de datos con Lagos de Datos Transaccionales
 29mServing a multi-platform Data Lake via Delta, Iceberg, Unity and Glue
 37mBuild a Modern Data Platform on AWS