Validation Pipeline for Summary Evaluation

summary
Built a reproducible LLM-as-judge pipeline that scores summaries on five expert-defined Likert dimensions, binarizes them (1–3 = bad, 4–5 = good), and reports agreement with expert labels. Reference metrics (ROUGE/BLEU/BERTscore) fail; hyperparam and model swaps give only marginal gains. Adding few-shot examples (2–3), forcing the model to give reasoning, and injecting negative controls (negations, number swaps, scrambled text) raises correctness agreement by >10% while completeness drops ~3% but stays above 90%.
AI-written summary · about
chapters (12)
- 0:00Intro and Goal
- 0:24Why Summary Quality Matters
- 1:16Dataset and Human Ratings
- 2:01Two Evaluation Approaches
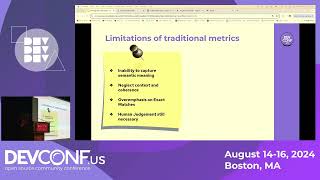
- 2:59Limits of Traditional Metrics
- 4:04Binary Agreement Scoring
- 5:59LLM Judge Pipeline Inputs
- 8:07What Improved Agreement
- 9:39Negative Control Summaries
- 11:17Results and Priorities
- 12:11Why Experts Stay In Loop
- 13:05Key Takeaways and Q&A
related talks
 25mEngineering Better Evals: Scalable LLM Evaluation Pipelines That Work
 38mThe Art of Compression: Crafting Insightful Summaries with LLMs
 34mBuilding Trust with LLMs
 32mA Practical Guide to LLM Evaluation
 33mThe Silent Crash:Why Your RAG Evaluation Metrics Are Lying to You
 41mJudge the Judge: Building LLM Evaluators That Actually Work with GEPA
 42mAdvancements in Evaluating Large Language Model Applications
 29mGenerative-AI: Usecase-Specific Evaluation of LLM-powered Applications