Treading Water in a Stream of Data
summary
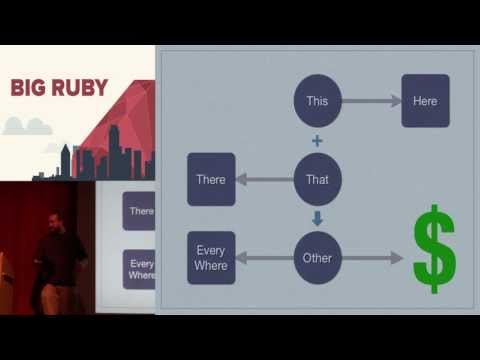
Argues for concrete ingestion patterns: prefer webhook plus polling fallback so missed deliveries are recoverable, avoid pure push for high‑volume feeds because missed packets are gone, and treat raw captures as the ground truth. Demonstrates using the github events API with the github archive as a backup, stores minimal‑processed records in avro files for robust MapReduce later, and uses simple queues like maildir/cron when reliability and simplicity beat complexity.
AI-written summary · about
chapters (22)
- 0:00Intro
- 1:07Data Junkie
- 1:38Survey Questions
- 2:50Big Data
- 4:21What is Big Data
- 5:23The Big Data Model
- 6:39Streaming Data
- 8:48Definitions
- 9:12Getting Data
- 10:02Polling
- 12:00Notification
- 22:32Rubygems
- 25:54GitHub Events
- 29:28Data Quality
- 31:05Storage
- 31:54hadoop
- 32:36avro
- 33:59why
- 34:20human error
- 35:28archive
- 36:29paranoia
- 38:49bonus track
related talks
 27mIngestify: Rethinking Ingestion for Complex Data
 43mEvent Sourcing dealing with an eventful past
 38mPostmortem: Evolution of an Event recording solution
 14mChange streams act on events in realtime
 01h 01mStream Data Processing for Fun and Profit
 27m"Write Once Stream Everywhere: Transforming Your Data into Events"
 14mHow not(!) to build real-time apps
 55mWorking with Webhooks