Trainium and Inferentia
summary
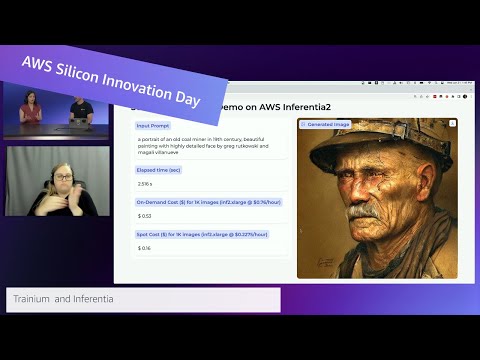
AWS Trainium and Inferentia details include TRN1/TRN1N with 512 GB HBM and 13 TB/s HBM bandwidth, Trainium UltraClusters scaling to >30,000 devices and six exaflops, and claimed 40% lower pre‑training cost for some customers. Inferentia2 Inf2 instances support chip‑to‑chip interconnects up to 10 TB/s per instance, run Stable Diffusion at about 2.5 seconds per image in the demo, and estimate $0.50 per 1,000 images on demand (cheaper on Spot).
AI-written summary · about
chapters (15)
- 0:00Introduction to Trainium and Inferentia
- 1:28What is generative AI?
- 3:15Foundational models and fine-tuning
- 5:45Trainium UltraClusters for LLM training
- 6:26TRN1 and TRN1N instance specs
- 7:51Data types in machine learning
- 10:00Deploying models at scale
- 10:41Stable Diffusion demo on Inf2
- 13:49Inference cost and performance
- 14:31Verifying Inf2 usage with Neuron-top
- 15:39LLM inference vs training similarities
- 16:41Inf2 chip-to-chip interconnect
- 17:44Optimizing LLM inference
- 19:51Customer experience and Neuron SDK
- 20:56Getting started with AWS Neuron
related talks
 25mSponsored Session: Accelerating GenAI Inference: From AWS Deep Learning...
 42mFine-tune and deploy LLMs from Hugging Face (AIM304)
 27mFoundation Models: Blueprints for success
 25mMoving Inference to Triton Servers
 49mMicroservices on InfiniBand: 800 Gbps in Distributed Training
 32mHow to choose the right instance type for ML inference
 12mAI-powered infrastructure:
 22mGenAI Training In Production: Software, Hardware & Network Considerations