Quantifying the growth and evolution of open-source communities with Apache Superset
summary
Claims a reusable, all-open-source data architecture that extracts Slack and GitHub into BigQuery (or Postgres), transforms with dbt, and visualizes in Apache Superset (Preset Cloud option tested); ingestion uses Airbyte connectors but falters at scale. Project finds 40,000+ GitHub stars and ~1,000 open issues, shows clear stargazer spikes around the 1.0/ASF graduation, produces Slack-based dashboards for shepherds and champions, and concludes Slack rate limits and connector maintenance are the main blockers.
AI-written summary · about
chapters (29)
- 0:00Introduction
- 0:58About me
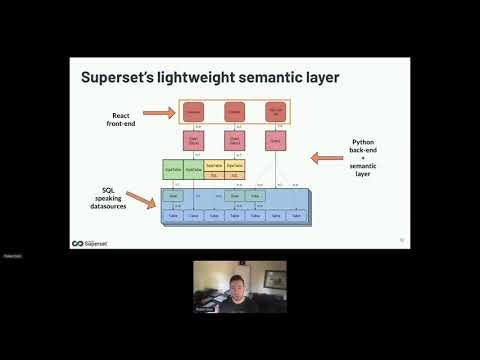
- 2:43What is Superset
- 3:39History of Apache Superset
- 5:02Features of Apache Superset
- 6:17SQL Alchemy
- 6:40Open Source BI
- 8:14Superset Architecture
- 8:48Explore Mode
- 9:04Inchart Analytics
- 9:42SQL Lab
- 9:54Dashboard
- 10:09Challenges
- 11:03Personas
- 13:10Superset
- 13:21Open issues
- 13:52Stargazers
- 14:09Growth Attribution
- 14:31Events Attribution
- 14:59Culture
- 16:19Data
- 18:13Our goals
- 22:57Preset Cloud
- 23:33Architecture
- 24:24What can we learn
- 24:56Shepherds and Champions
- 26:33Slack Dashboard
- 27:15Learnings
- 31:17Wrap up
related talks
 29mOpen Source Powers The Modern Data Stack
 40mDiscovering Emerging Open Source Communities Through...
 32mVisualize more, spend less: Unlock data visualizations with Apache Superset
 25mHow to Grow & Mentor an Open Source Community & Achieve Collaboration with Over 170 Listed Corpor...
 08mAll eyes on Open Source: Monitoring community sovereignty
 43mDon't Start Over, Start Left: Choosing the Right Open Source...
 29mState of AsyncAPI Community
 01h 03mWhat can we learn from 750 billion GitHub events and 42 TB of code