Smarter word generation in LLMs: Guiding sampling through output probability distributions
summary
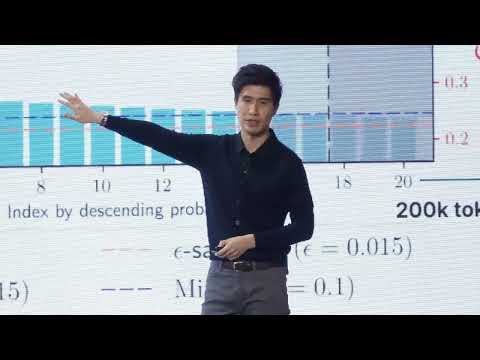
Introduces a decoding rule called Pillars that sets a dynamic cutoff equal to the sum of squared token probabilities so only tokens with p >= sum(p^2) are sampled, removing tunable knobs like top‑K/top‑P and avoiding sorting. Implements on Llama 3 instruct via Hugging Face and publishes code on GitHub. Tests on creative writing, logical reasoning and math problems show higher accuracy across temperatures, controlled output length, roughly 0.19s per token vs ≥0.2s for others, and a typical sampling set of about four tokens under focused distributions.
AI-written summary · about
chapters (9)
- 0:00LM nondeterminism challenges
- 1:14Token probability distributions
- 4:46Traditional sampling limits
- 9:07Introducing pillars sampling
- 13:24Pillars for ML engineers
- 16:37Deterministic final answers
- 17:20Evaluating pillars
- 20:38Pillars improves reliability
- 21:43Summary and resources
related talks
 46mThings you never dared to ask about LLMs
 46mUnder the Hood of LLMs — all those questions you never dared ask about them
 39mHallucination-Free LLMs: Strategies for Monitoring and Mitigation
 30mTaking Control of LLM Outputs: An Introductory Journey into Logits
 27mWhich Is To Be Master? Understanding LLM Tokenization
 11mEffective Sequential Monte Carlo for Language Model Probabilistic Programs
 46mBeyond Basic Prompting: Supercharging Open Source LLMs with LMQL's Structured Generation
 55mLessons Learned From Implementing Generative AI Solutions